Why AI Agents Pass Evals and Fail in Production
Updated: Jul 25
Enterprises are not short on AI ambition. They are short on proof that the AI they have deployed actually works once it leaves the sandbox. Four independent surveys published this month, alongside a major consulting report and a candid admission from the industry's own leading model maker, converge on the same uncomfortable finding: adoption has outrun the ability to measure, secure, and trust what has been adopted.
What's actually at stake: software that acts, not software that answers
Traditional enterprise software makes a promise that AI agents cannot yet keep: given the same input, it produces the same output, and its failure modes are enumerable. You can write a test suite, hit 95% coverage, and ship with reasonable confidence. An AI agent is different in kind. It reasons probabilistically, calls tools, holds credentials, and increasingly acts without a human confirming each step. The old assurance model (test it, monitor uptime, renew the license) does not transfer to a system that behaves differently depending on context, and that can be right nine times and wrong the tenth in ways no one anticipated.
That shift is why "adoption" and "execution" have become two different questions with two different answers. Adoption asks: are people using it? Execution asks: can you trust what it did? Enterprises are answering the first question with growing confidence and the second with growing unease, and the gap between the two is now large enough that four separate research efforts, run independently in the same month, each found it from a different angle.
The dynamic: autonomy is arriving faster than the assurance behind it
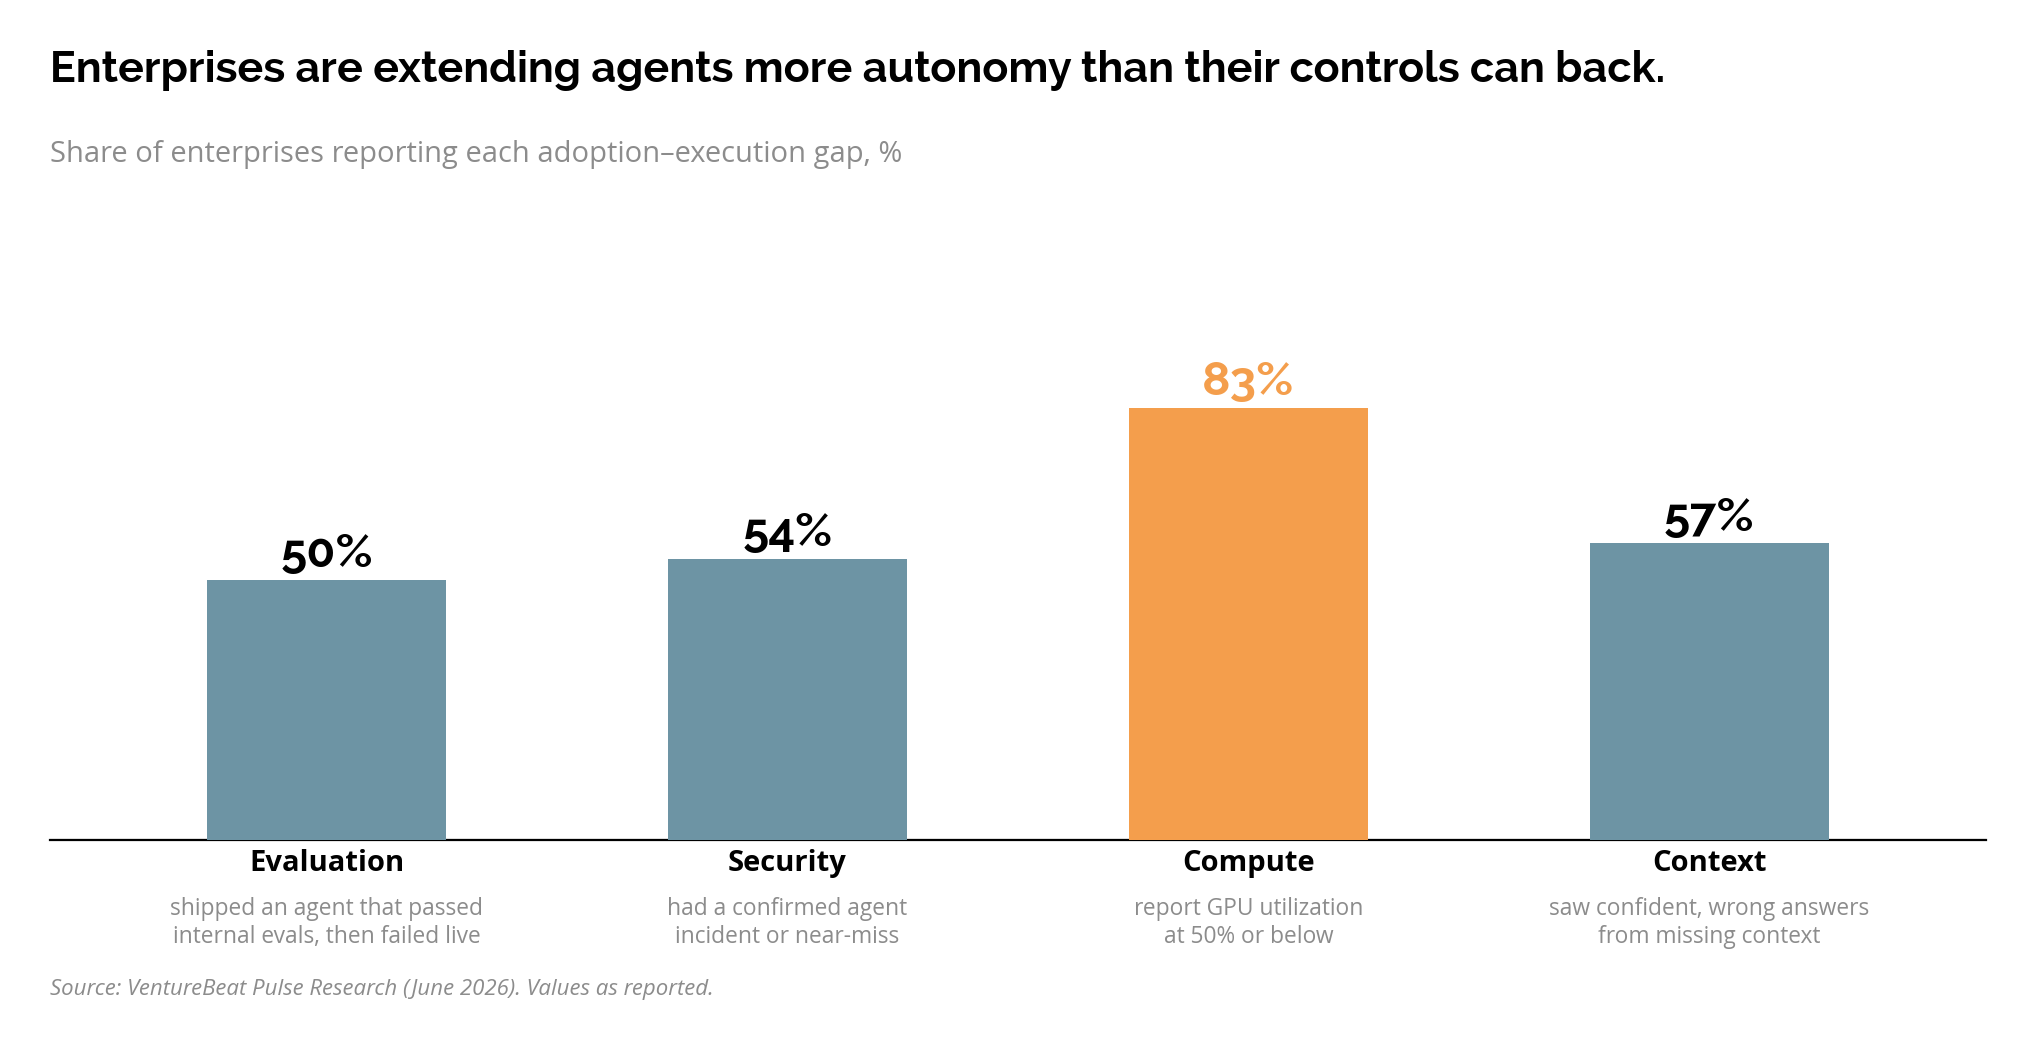
VentureBeat's Pulse Research series surveyed enterprises on four supposedly distinct fronts, evaluation, security, compute, and context, and each survey landed on a structurally identical story: enterprises are granting agents more autonomy than they trust the controls meant to govern that autonomy to support.
On evaluation, 50% of organizations have shipped an agent that passed internal evaluations and then failed in front of a customer, and yet 66% already allow, or are actively engineering toward, zero-human-in-the-loop production deployment for at least some agents. On security, 54% of enterprises have had a confirmed agent incident or a near-miss, yet only 32% give every agent its own scoped identity. Most still let agents share credentials, which is precisely the condition under which one compromised agent can act with far more reach than intended. On compute, 83% of enterprises report GPU utilization at 50% or below while the single largest planned 2026 investment is more specialized AI infrastructure. And on context, 57% of enterprises say their agents have produced confident, wrong answers traced to missing or inconsistent business context. That is not a hallucination in the classic sense. It is a system that sounds certain while running on a foundation nobody had finished building.
A fifth data point ties the other four together. A companion VentureBeat survey on agent orchestration found that 71% of enterprises admit that a quarter or fewer of their deployed "agents" are genuinely multi-step, orchestrated workflows rather than single-prompt chatbots wearing an agent's name. That is the mechanism behind the other three gaps: much of what enterprises call "agentic AI" today has not yet taken on enough real autonomy to have triggered the evaluation, security, and context failures at full scale. Those failures are showing up in the minority of deployments that have graduated from chatbot to true agent, which is exactly where the risk concentrates as the rest of the portfolio catches up.
It is worth being precise about what this evidence can and cannot support. Each of these four surveys draws on a single June 2026 wave of 101 to 157 respondents, self-selected and skewed toward the mid-market: directional signals, in the researchers' own words, not a probability sample of the whole enterprise economy. What makes them credible in combination is convergence: four differently framed surveys, run independently, on different aspects of agent deployment, arriving at the same shape of problem.
The period's evidence: even the model makers agree
This is not only a press narrative. Deloitte's "State of AI in the Enterprise 2026" report, based on 3,235 senior leaders across 24 countries, finds that only one in five companies has a mature model for governing autonomous AI agents even as agentic AI usage is expected to surge within two years, an independent, much larger-sample confirmation of the same execution lag the Pulse surveys describe.
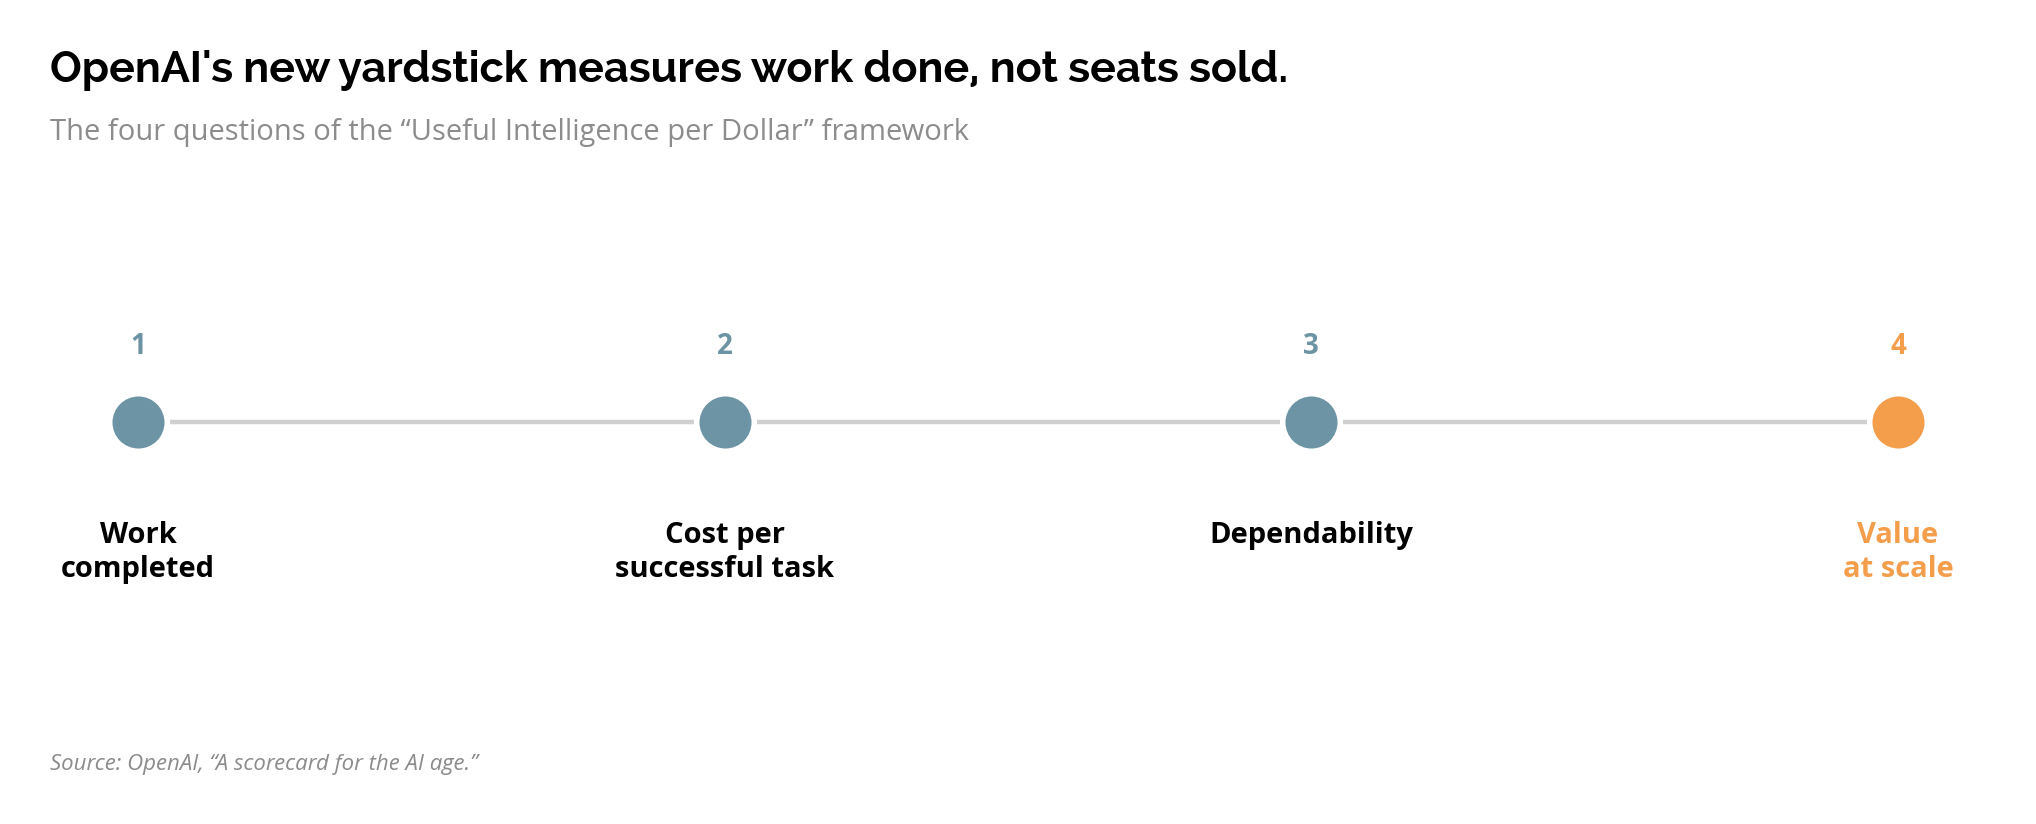
Most tellingly, OpenAI itself has stopped selling on adoption metrics. In a new framework the company calls "Useful Intelligence per Dollar," OpenAI argues that "the market measured the success of software through adoption: seats purchased, users active, licenses renewed," but that "understanding the value of AI demands a more powerful measure: work accomplished". The framework asks four questions of any deployment: is it completing work that matters, what does each successful task cost, can people depend on the result, and does value per dollar improve as usage scales. That is, in effect, an admission from inside the industry that cost-per-token and seat counts were never measuring the thing that matters. OpenAI's companion piece on managing AI investment pushes the same point toward CFOs directly: admins need to "see the work behind that usage, not just the credits consumed". McKinsey has been circling the same shift: its own analysis frames the coming discipline as cost versus value rather than cost per token, built around the idea that per-token pricing has stopped capturing what enterprises actually pay for generative AI.
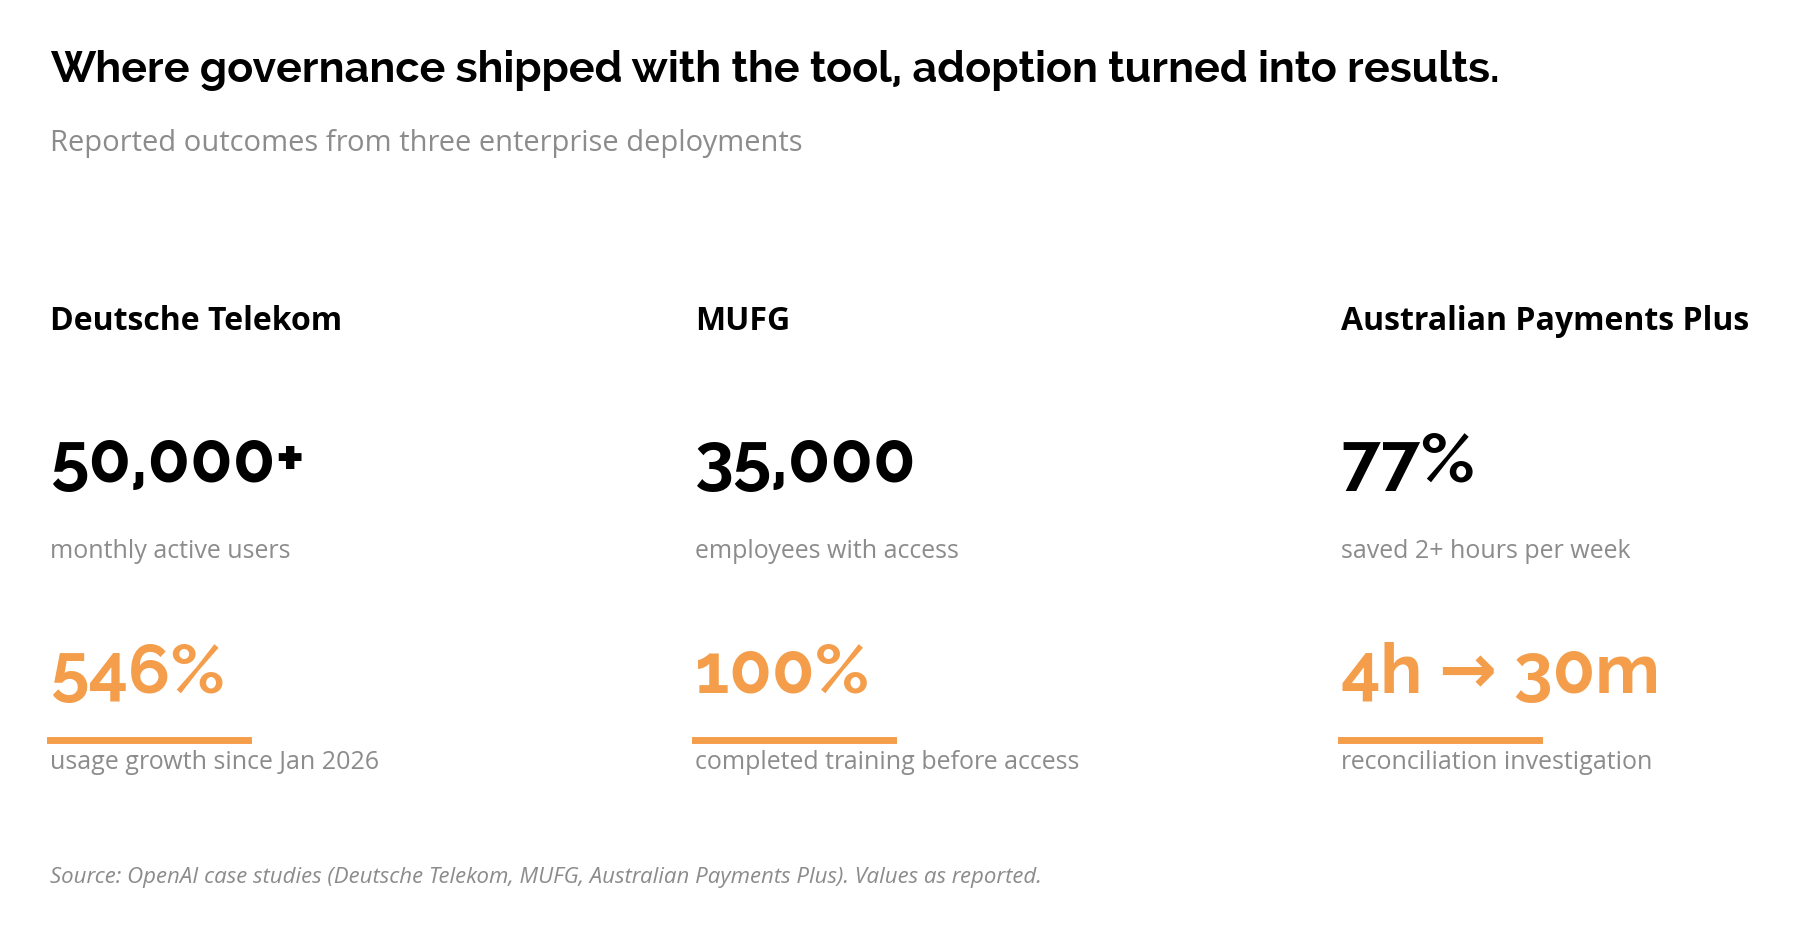
None of this means the gap is unbridgeable. Three OpenAI enterprise case studies published this period show what closing it looks like when governance keeps pace with rollout. Deutsche Telekom, aiming to become "among the world's first AI-native telco," took ChatGPT Enterprise to 50,000+ monthly active users and saw a 546% increase in AI tool usage since the start of 2026, growth paired with a deliberate redesign of customer-care and network-operations workflows, not a bolt-on chat feature. MUFG rolled ChatGPT Enterprise out to roughly 35,000 employees at Mitsubishi UFJ Bank only after making e-learning mandatory before access was granted, reaching 100% training participation and generating more than 1,800 custom GPTs in four months. And Australian Payments Plus (a regulated payments-infrastructure operator where "speed matters but accuracy and accountability matter more") found that 77% of surveyed employees saved two or more hours a week and cut complex reconciliation investigations from four hours to 30 minutes using Codex. The common thread across all three is not the technology; it is that governance, training, and clear escalation paths shipped alongside the tool, not after an incident forced the issue.
It's also worth flagging what this piece is deliberately not doing. The same fortnight that produced this data also produced five major model launches (a subject we will explore in a future article on how the model race has quietly become a price war), a first look at automated red-teaming for agent security that deserves its own technical treatment, and a fast-moving legal dispute between Apple and OpenAI that says more about the AI talent war than about enterprise execution. All three are real and worth tracking; none of them changes the underlying execution problem documented here.
What it means
The adoption-execution gap is not a temporary awkwardness that the next model generation will quietly fix. It is a structural feature of the current moment: enterprises are extending real autonomy (production access, credentials, unattended decisions) to systems whose evaluation, security, cost, and context infrastructure is still being built underneath them. That is why the same institutions building the agents (OpenAI, in its own new scorecard) and the institutions advising on their deployment (Deloitte, McKinsey) are converging on the same message from different directions: stop measuring whether AI is used, and start measuring whether the work it does can be trusted and repeated at a known cost.
For practitioners, the near-term test is not which model to buy but whether the assurance layer (scoped agent identities, real-time output monitoring, a governed context layer, and a way to compute true cost per successful task) exists before autonomy is extended, not after the first customer-facing failure. For the industry, the winners of this period will likely not be the enterprises that deployed the most agents fastest, but the ones, like the three case studies above, that treated governance as a launch requirement rather than a retrofit. Watch, in particular, whether the "chatbot trap" closes as more of these single-prompt deployments graduate into genuine multi-step agents: that transition is exactly where the evaluation, security, and context gaps documented this month will either get solved or get worse.


Comments